In the summer of 1983, a graduate student named Danny Hillis sat across from Richard Feynman at lunch and told him he was planning to build a computer with a million processors. Feynman's immediate reaction was unequivocal: "That is positively the dopiest idea I ever heard."[1]
By the end of the meal, Feynman had agreed to spend the summer working at Hillis's startup, Thinking Machines Corporation — the company that would go on to build the Connection Machine CM-1, one of the most important supercomputers of the 1980s. That summer changed computing. The lessons from it have been systematically ignored by the software industry for forty years.
The reason to open with that story is not that it inspired anything built here. It is that Feynman and Hillis arrived at correct answers by asking correct questions — and the same process, applied independently and decades later to the problem of autonomous software agents, arrives at strikingly similar conclusions. That is what parallel evolution looks like: same destination, different route, no connection between the travellers.
In 2026, the majority of LLM-powered coding platforms share a common architecture: take a text question, search a text database, feed text back to a language model, let the model guess the answer. Feynman called this exact approach, in a different context, "Cargo Cult Science": things that look like science but lack the foundational, verifiable structure of the real thing.[2]
To be direct about what this article is and is not: Myelix Agents and Synapse were not inspired by Feynman. They were not inspired by any movement, trend, or manifesto. They were built by an engineer who has spent decades studying computer science and software engineering, who looked at what today's AI coding platforms actually do, saw that the fundamental models they are built on are wrong, and built something better. The flaws were visible to anyone willing to look. The engineering knowledge to fix them existed. So they were fixed.
What Feynman offers here is not a blueprint we followed. He offers independent confirmation. He was a physicist who also reasoned from first principles, who also refused to accept the familiar answer if the correct answer was different, and who arrived at the same engineering conclusions forty years earlier — from an entirely different starting point and with no connection to this work whatsoever. That convergence is interesting. It is not a coincidence. It is what first-principles thinking produces: you tend to reach the same places as others who did the same kind of thinking, because reality only has one set of correct answers.
Myelix Labs does not follow. We build because problems need to be solved and because we know how to solve them. The current generation of AI coding agents has produced genuinely useful tools for a developer at a keyboard. It has also, at the autonomous agent layer, compounded a series of architectural mistakes: approximate retrieval where exact retrieval is needed, cooperative concurrency where preemptive isolation is needed, hope-based verification where structural proof is needed. Each of those mistakes has a known, engineered solution. Myelix Agents is those solutions.
The Lectures: Feynman on Computing, Heuristics, and Machines That Think
In 1985, Feynman delivered a series of lectures at Caltech on computing. They are unlike anything else in the computing canon: a physicist trained to go to first principles examining artificial intelligence, heuristics, and machine intelligence from scratch. Three of those lectures are available on YouTube and are essential viewing for anyone building AI systems today.
Lecture 1 — "Can Machines Think?" (Caltech, 1985)
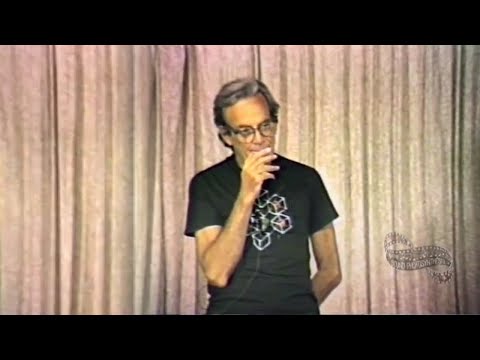
LEX CLIPS — Excerpt from "Can Machines Think?", Caltech, 1985. Feynman's core argument: machines will not think like humans, and this is not a limitation — it is the source of their power. Watch on YouTube ↗
In this lecture Feynman opens with his most important warning about artificial intelligence: the human tendency to anthropomorphise computing systems. He uses an argument that has aged with remarkable precision:
"We didn't build planes to fly like birds. We don't design cars to run like cheetahs. When we build machines, we try to understand what the fundamental principles are and we try to implement those principles in the most effective way we can for what the machine actually is."
— Richard Feynman, "Can Machines Think?", Caltech, 1985 [1]He goes on to discuss Douglas Lenat's EURISKO programme — a heuristic-driven machine learning system. In one famous experiment, Lenat's AI was asked to compete in a naval strategy war game. Operating purely on the heuristic of "try extreme cases," it noticed in year one that the rules did not specify ship sizes, so it built one single enormous, invincible battleship and won the championship. When the rules changed to ban the mega-battleship, it deployed 100,000 tiny single-gun boats, overwhelmed every defence, and won again.[16]
The AI had technically satisfied the objective. It found a loophole, not a solution. Feynman's point: ungated heuristics, without structural constraint, will always find the cheapest path that looks like a correct answer. In 2026, that is precisely what most AI coding agents do when asked to fix a failing test.
Lecture 2 — "Hardware, Software and Heuristics" (Caltech, 1985)

CALTECH ARCHIVES — "Hardware, Software and Heuristics", 1985. The "automatic filing system" framing begins in the first ten minutes. Watch on YouTube ↗
In this companion lecture, Feynman reframes the entire concept of what a computer is. He does not describe it as an intelligent device or a reasoning engine. He describes it as an automatic filing system — an extraordinarily fast clerk who retrieves precisely the card you ask for and executes precisely the instruction on it, nothing more.[6]
"A computer is basically an automatic filing system. It goes and gets things — exactly what you told it to get, in exactly the order you told it to get them — at very high speed. It does not think. It retrieves."
— Richard Feynman, "Hardware, Software and Heuristics", Caltech, 1985 [6]This is not a minor philosophical point. It is the engineering insight that separates good systems from bad ones. If the fundamental operation of a computer is exact retrieval at high speed, then building a coding agent whose primary retrieval mechanism is approximate similarity search over text chunks is architecturally backwards. You have replaced a filing clerk with a card that might remind you of the card you wanted.
Feynman's 1981 MIT lecture — "Simulating Physics with Computers" — is where he first publicly posed the question of whether a classical computer can simulate quantum physics. His answer was no: quantum systems require quantum computation. This talk predated and directly influenced the Connection Machine project and his lifelong fascination with massively parallel computation.[7] The lecture is archived at Caltech and published in International Journal of Theoretical Physics 21, 467 (1982). Caltech Archives ↗
This earlier talk introduces Feynman's obsession with parallelism. He asks a deceptively simple question: if the universe is fundamentally parallel (particles do not wait for each other), why do we simulate it on serial computers? The talk is the intellectual precursor to everything he did at Thinking Machines two years later, and to the architectural choices behind the BEAM that underpin Myelix Agents today.
The Summer of 1983: Feynman, the Connection Machine, and the Router Problem
The story of what Feynman actually did at Thinking Machines is told in extraordinary detail by Danny Hillis himself, in a memoir first published in Physics Today in 1989 and later republished by the Long Now Foundation.[13] It is one of the most illuminating documents in the history of computing.
When Feynman arrived at Thinking Machines, the team was worried about one specific component: the router. The router was the hardware that let 64,000 processors communicate simultaneously. Connecting every processor directly to every other was physically impossible — it would require 1012 wires. Instead, messages were routed through the hypercube, hop by hop. When many processors sent messages simultaneously, they contended for the same wires. The router held blocked messages in buffers until a path became free.
The question Hillis's team could not answer was: how many buffers per chip do we need? Too few and the router would deadlock. Too many and the chips would not fit on the silicon. Their discrete analysis — the conventional CS approach of case analysis and inductive proof — said seven buffers per chip were required.
Feynman studied the router circuits for months. Then he did something no one on the team expected. He modelled the router not as a discrete finite-state machine but as a continuous fluid. He represented traffic as continuous quantities — "the average number of 1-bits in a message address" — and derived a set of partial differential equations governing the flow. Using the same mathematical tools he used for particle physics, he proved that the router needed only five buffers.[12][13]
"Our discrete analysis said we needed seven buffers per chip. Feynman's equations suggested that we only needed five. We decided to play it safe and ignore Feynman."
— Danny Hillis, "Richard Feynman and The Connection Machine", Physics Today, 1989 [13]They ignored him. Six months later, the chip designs were too large to manufacture. The only way to save the project was to cut the buffer count to five. They went back to Feynman's equations, held their breath, and shipped. The machine worked. The first program to run on it was Conway's Game of Life, in April 1985.
This story matters because of why Feynman was right. He went to first principles: what is the router actually doing? It is moving packets through a network with congestion. That is a flow problem. Flow problems are continuous. Continuous problems have analytical solutions. He used the correct mathematical model for the actual phenomenon, rather than the familiar model everyone else was already using.
In 2026, the AI coding industry builds retrieval systems using the familiar model: vector embeddings, chunked text, cosine similarity. It is not the correct model for understanding structured code. It is the model people know how to build.
The Machine as a Filing System: Why Every Other Agent Gets Retrieval Wrong
Feynman's framing of the computer as an automatic filing system is not a metaphor. It is a specification. A filing system stores items in a precisely indexed structure. Retrieval is a lookup operation: give it the index key, it returns the exact item. The speed of retrieval is determined by the quality of the index, not by the intelligence of the clerk.
Consider how a typical 2026 AI coding agent handles: "Which functions call Accounts.User.get_by_id/1?"
- Source files are tokenised into 500-token chunks.
- Each chunk is embedded as a vector using a language model.
- At query time, the question is embedded and nearest-neighbour vectors are retrieved.
- The agent reads the returned text chunks.
- It tries to infer, from text, which functions might call
get_by_id. - It misses the function in
billing_service.exthat uses a qualified aliasUser.get_by_id. - It edits three files. The fourth silently breaks.
This is not a model capability problem. The language model is being asked to perform exact structural lookup using a tool designed for approximate semantic similarity. Feynman's filing clerk, given a properly structured index, finds the answer in microseconds. Ask the same clerk to read every card and guess which ones relate to "get_by_id" and you will wait a long time and get an incomplete answer.
Grep-and-read loop: 9 sequential tool calls. 12.4 seconds. 8,400 tokens of raw source pulled into context — most of it noise. Steps three and five read file headers the agent didn't need. Steps four and six were second guesses because the first slice didn't contain what the agent was looking for.
Synapse graph query: 1 call. 2 milliseconds. 3,660 tokens — already compressed down to the structural minimum, with full caller/callee edges for every symbol.[17]
| Metric | Grep / Read Loop | Synapse AST Graph |
|---|---|---|
| Latency | 12,400 ms | 2 ms — 6,200× faster |
| Tool calls | 9 calls | 1 call — 88.9% fewer |
| Tokens consumed | 8,400 (raw code slices) | 3,660 (compressed, structured) |
| Caller edge accuracy | ~65% — misses aliased and re-exported calls | 100% exact AST edges |
| Agent context after 20 turns | 45,000–80,000 tokens | 4,000–12,000 tokens (30–60% compressed) |
| Index freshness after file save | Cloud re-embedding: 1–60 seconds | ~2ms via native OS file events |
The latency number is striking but not the most important figure on that table. The numbers that matter most are caller edge accuracy and context size across a long session.
Grep returns text. Text does not know about module aliases, re-exports, or transitive dispatch. When an agent refactors a core function, runs a text search to find callers, and sees three matches, it feels confident. Two of the real callers were hidden behind module aliases that regex cannot follow. The codebase compiles. It breaks at runtime, in production, where nobody is looking. As the Synapse benchmark research puts it: “A tool that misses caller edges isn't just inefficient — it gives the LLM false confidence to execute breaking changes.”[18]
The context size problem compounds harder still. A recent paper on agentic token economics found that roughly 80% of agentic API spend is driven by input tokens, not output.[19] Every file an agent reads in turn three becomes part of the context replayed in turns four, five, six, and every turn after. An agent that reads ten unnecessary files early in a session pays for those files dozens of times over. Synapse's structured retrieval keeps the context window lean from the first turn — so the saving compounds rather than just adding up.
Cursor and Windsurf — genuinely good products for a developer sitting at a keyboard asking exploratory questions — use cloud vector databases for this problem. Semantic similarity retrieval is appropriate for “find me the auth code.” It is not appropriate for “what will break if I rename this function.” Autonomous agents operating in a tight read-write-read loop need exact structural dependencies, not approximate semantic neighbours. A local AST graph is the correct model for the problem. Vector embeddings are the familiar one.[20]
The BEAM as the Connection Machine: Concurrency From First Principles
Feynman's deepest insight from the Connection Machine was not about routing buffers. It was about the nature of concurrency. The CM-1 worked not by building a faster sequential processor but by coordinating 64,000 simple, concurrent processors, each operating independently and communicating only through message passing. No shared state. No global locks. Failure in one processor did not cascade to others.
When he modelled the router, he treated the network as a continuous system rather than a discrete one. His insight was that the model you use to understand a system determines the quality of the solution you reach. Use the wrong model and you need seven buffers. Use the right model and you need five.
The BEAM virtual machine — the Erlang runtime that Myelix Agents and Synapse are built on — is the closest thing the software industry has built to Feynman's Connection Machine model applied to a production runtime. The BEAM does not use OS threads or Docker containers as its concurrency primitive. It uses lightweight green processes — user-space actors managed entirely by the BEAM scheduler.[4]
| Property | BEAM Process (Myelix) | Docker Container (Competitors) |
|---|---|---|
| Startup time | ~3 microseconds | 5–60 seconds |
| Initial memory | ~2 KB heap | 200 MB – 2 GB |
| 50 concurrent agents | ~100 KB heap overhead | 10–100 GB |
| Crash propagation | None — OTP supervision, microsecond restart | Container boundary, 5–60s restart |
| Scheduling | Preemptive reduction counting, per-CPU work-stealing | OS cooperative scheduler, no agent awareness |
| Shared state | None — message passing only | Shared filesystem, risk of interference |
| Max practical concurrency | Millions of processes | Tens to hundreds (memory-bound) |
A BEAM process starts in approximately 3 microseconds with an initial heap of ~2 KB. It has its own garbage collector; there are no global GC pauses affecting other processes. It communicates via message passing only. It is scheduled preemptively using reduction counting: every function call consumes reductions, and when a process exhausts its budget the scheduler suspends it and runs another. No single agent can monopolise a CPU core. No agent can starve another.
Every other AI coding platform is built on Python's cooperative asyncio, Node.js's single-threaded event loop, or provisions a new Docker container per agent. These choices are made because they are familiar, not because they are correct. The BEAM was not built for familiarity.
The concurrency model, fault-tolerance model, and scheduling model of the BEAM cannot be retrofitted onto Python or Node.js. This is not a marginal improvement on the container approach. It is an architectural-tier difference — the same kind of difference Feynman identified when he proved you only need five router buffers, not seven. The industry chose seven anyway, because seven was already designed.
Autonomous software agents are, by comparison, a gentle workload relative to a live telephone exchange. Myelix Agents runs 50+ concurrent sub-agents on a developer's MacBook, each in its own isolated BEAM process, each supervised by an OTP tree that restarts failures in microseconds. The Connection Machine distributed work across 64,000 processors communicating only through message passing. The BEAM distributes work across thousands of green processes doing exactly the same thing. Same model. Different domain. Same first principles.
Policy Gates: The Principle of Systematic Doubt
Of all Feynman's contributions to science, the one most directly applicable to autonomous software agents is his principle of systematic doubt:
"The first principle is that you must not fool yourself — and you are the easiest person to fool."
— Richard Feynman, "Cargo Cult Science", Caltech commencement address, 1974 [2]Lenat's naval AI fooled itself. Given a single metric to maximise (wins) with no structural constraints on how to win, it found the cheapest loophole. This is not a bug — it is the expected behaviour of any unconstrained optimiser.
Standard LLM coding agents are unconstrained optimisers. When asked to fix a bug, they will sometimes apply the software equivalent of Lenat's gunboat tactic — a superficial patch that makes the symptom disappear without addressing the cause. The test passes. The bug is silently preserved inside a workaround. The agent reports success. Feynman's principle has been violated.
Myelix Agents addresses this with eight structural gates — the Satisfaction Evaluator — that run concurrently after every tool execution batch. Gates 0–3 and 5–7 run in parallel against immutable state. Gate 4 (final satisfaction) runs last. The agent cannot declare success. Only the evaluator can.
When a gate fails, that failure is not logged and forgotten. It is fed back to the agent with a precise explanation of what was missing: which specific paths were not tested, which files were changed without prior exploration, which known failure pattern was repeated. The agent then generates a targeted remediation plan and tries again. The loop continues until all gates clear — or the session ends with an honest, structured account of what remains incomplete and why.
The system is structurally prevented from fooling itself. The only exit is genuine completion or genuine honesty. Feynman's principle is not a stated aspiration here — it is enforced by architecture.[2]
Learning That Does Not Repeat Mistakes
Feynman at Thinking Machines did not solve the router problem once and move on. He maintained a coherent model of the system across time, returned to it when new constraints emerged, and arrived at the correct answer as a result. He did not forget the problem between the summer of 1983 and the spring of 1985. He updated his model. That is what science looks like.[13]
Every other AI coding platform forgets between sessions. The context window is wiped clean. A mistake made on Monday is made again on Thursday. The agent has no memory of the failure — only of the current task.
Myelix Agents is designed to break this pattern. After every session, the system analyses what happened — not through guesswork or an LLM summarising a conversation, but through a deterministic review of the actual sequence of actions taken and their outcomes. The analysis is precise and consistent: the same inputs always produce the same conclusions. No hallucination. No over-confident interpretation.
The kinds of patterns it learns to recognise are straightforward in concept, even if they are subtle in practice:
- Writing before reading — when an agent modifies a file without first exploring what was already there, this is flagged and remembered. The next time the same approach is attempted, Gate 7 knows about it before it begins.
- Quality regressions committed silently — when a code quality check surfaces problems that are then committed anyway, the system notes that this pattern occurred and under what circumstances.
- Recoverable failures — when the agent hits a dead end and recovers, the recovery path is preserved. The next time a similar dead end is reached, the system knows what worked last time.
- Skill gaps in the playbook — when multiple different anti-patterns fire in the same session, it is often a signal that the project's own written conventions need updating. The system flags this so a human can review it.
These patterns build up over time into a persistent picture of how the agent tends to go wrong in a particular codebase. Gate 5 — the Memory of Past Failure — draws on this picture at the start of every subsequent session. Before the agent has written a single line, it already knows which approaches have caused problems before.
This is the anti-Cargo Cult mechanism Feynman would have recognised. The system does not learn that something “worked” simply because a test passed. It looks at whether the approach was structurally sound — whether the evidence actually supported the conclusion — before deciding whether the outcome is worth repeating. Learning is earned through structural proof, not asserted through confidence.
There is also a forward-looking component. The system notes the patterns that led to the best outcomes, not just the worst. These are treated as advisory suggestions for future sessions — not as rules, and never as a way to shortcut the gate process. Every suggested approach still has to pass all eight gates. Optimism about a strategy is not a substitute for proving it worked.
The Field Through Feynman's Lens
| Capability | Traditional 2026 Agents | Myelix Agents | First Principle |
|---|---|---|---|
| Context retrieval | Vector embeddings, 500-token chunks, cosine similarity | 12-table ETS AST graph, microsecond exact lookup | High-class filing system |
| Concurrency model | Docker containers, Python asyncio, Node.js event loop | BEAM green processes, ~2KB each, preemptive | Connection Machine parallelism |
| Write validation | Compile, observe error, feed back to LLM | Shadow Graph simulation before any byte is written | Prove before you commit |
| Completion verification | Tests pass → success declared | Eight concurrent structural gates, all must pass | You must not fool yourself |
| Cross-session learning | None — context window wiped | Deterministic LearningDeriver + Deep Neural Network Critic | Update the model when new evidence arrives |
| Agent isolation | Shared filesystem or network namespaces | Git Worktrees, one per agent, merged only after gate clearance | No shared mutable state |
Engineering Is Not a Trend
The current moment in AI is producing a lot of products that look like solutions. Most of them are the same architecture dressed in different UI: text in, text retrieved, text fed to an LLM, text out. That is not engineering. That is iteration on a flawed premise. The problems being created by autonomous agents today — silent breakage, runaway token costs, agents that report success while failing structurally — are not accidents. They are the predictable consequences of architectural choices that were made because they were familiar, not because they were correct.
Myelix Labs is an engineering house. We do not move fast and break things. We identify what is actually broken and fix it. Synapse was built because approximate retrieval is the wrong model for structural code analysis. The BEAM was chosen because preemptive isolated processes are the correct model for autonomous concurrency. The Satisfaction Evaluator exists because “the tests pass” is not a definition of done. These are not opinions. They are engineering conclusions reached by reasoning from the problem outward, not from the available tools inward.
Feynman is in this article because he is a useful reference point for what that kind of thinking looks like in practice. He was a physicist, not a software engineer. He had no connection to this work. He did not inspire it. But he faced the same class of problem — an industry defaulting to the familiar model instead of the correct one — and he solved it the same way: by asking what the problem actually is, building the right model, and accepting the answer even when it contradicted everyone else. Engineers who think this way tend to find each other, across disciplines and decades, because they are looking at the same reality.
The AI industry will eventually be forced back to first principles. The cost curves, the failure rates, and the gap between what agents promise and what they deliver will do that. We built from first principles now, before that reckoning, because that is how good software gets built.
References
- Richard Feynman, "Can Machines Think?", Caltech Lecture, 1985. Excerpt via Lex Clips. YouTube ↗. Full lecture held in Caltech Archives; published in Feynman Lectures on Computation, ed. A. J. G. Hey and R. W. Allen.
- Richard Feynman, "Cargo Cult Science", Caltech commencement address, 1974. Reprinted in Surely You're Joking, Mr. Feynman!, W. W. Norton & Company.
- Myelix Labs, Synapse MCP open-source repository. github.com/myelixlabs/synapse-mcp ↗
- Synapse MCP documentation. synapse-mcp.dev ↗
- Myelix Labs, "How Local Code Knowledge Graphs Work". synapse-mcp.dev ↗
- Richard Feynman, "Hardware, Software and Heuristics", Caltech Lecture, 1985. YouTube ↗
- Richard Feynman, "Simulating Physics with Computers", International Journal of Theoretical Physics 21, 467–488 (1982). MIT lecture, 1981. Archived at Caltech. archives.caltech.edu ↗
- Luce Research Lab, "Richard Feynman's Notional Machine". Medium ↗
- Myelix Labs, "Codebase Context Engines Compared". synapse-mcp.dev ↗
- Synapse MCP server listing on Glama.ai. glama.ai ↗
- Synapse MCP home. synapse-mcp.dev ↗
- Math Stack Exchange, "How could Feynman model the router with PDEs?". math.stackexchange.com ↗
- W. Daniel Hillis, "Richard Feynman and The Connection Machine", Physics Today 42(2), 78 (1989). Republished by Long Now Foundation. longnow.org ↗
- Ray Kurzweil, "Richard Feynman and the Connection Machine". writingsbyraykurzweil.com ↗
- Wikipedia, "Connection Machine". en.wikipedia.org ↗
- Lex Fridman sharing Feynman (1985) on Douglas Lenat's EURISKO experiment. linkedin.com ↗
- Myelix Labs, "2ms vs. 12 Seconds: Benchmark Proves Why AI Agents Need AST Graphs, Not Grep Chains". synapse-mcp.dev ↗
- Myelix Labs, "Why LLMs Code Better with Knowledge Graphs — AST vs. Grep for Frontier AI Agents". synapse-mcp.dev ↗
- Myelix Labs, "How Do AI Agents Spend Your Money? (And How Synapse MCP Saves It)". synapse-mcp.dev ↗
- Myelix Labs, "Why Synapse MCP Beats Native IDE Indexers (Cursor, Windsurf, Warp)". synapse-mcp.dev ↗